> For the complete documentation index, see [llms.txt](https://docs.uptiq.ai/llms.txt). Markdown versions of documentation pages are available by appending `.md` to page URLs; this page is available as [Markdown](https://docs.uptiq.ai/control-center/evals/online-eval.md).
# Online Eval
Monitor evaluator scores for live production executions.
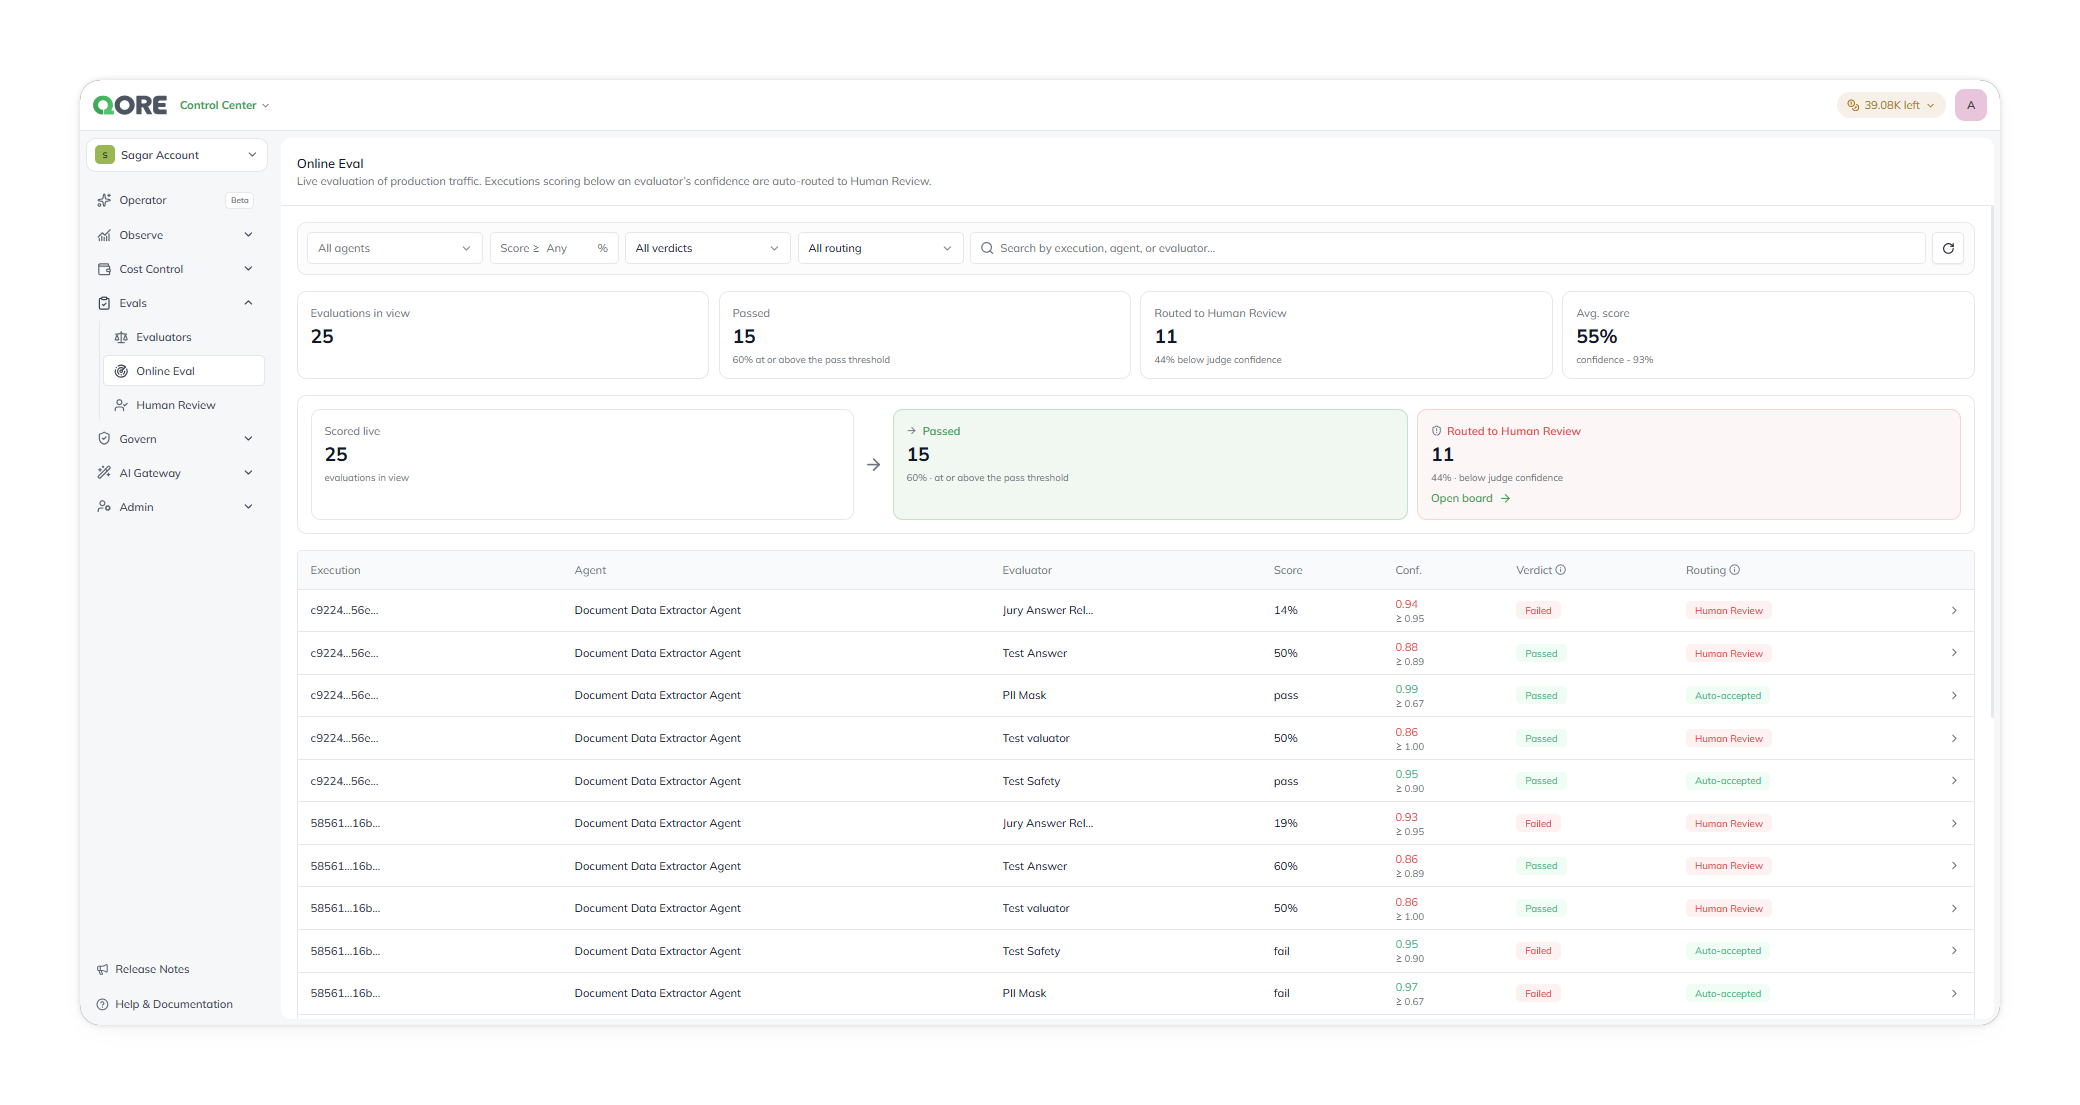
Online Eval scores live production traffic. Open **Evaluation & Quality → Online Eval** to view scored executions and their routing.
Online Eval scores live production executions.
Filter by agent, minimum score, verdict, or routing. Search by execution, agent, or evaluator.
For the selected time range, the summary shows:
* Scored executions
* Executions that passed at or above the pass threshold
* Executions routed to Human Review below judge confidence
* Average score
Select **Open board** to open Human Review.
### Scored execution fields
| Column | What it shows |
| ------------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| **Execution** | The execution ID. |
| **Agent** | The agent that produced the output. |
| **Evaluator** | The evaluator that scored it, such as *PII Mask*. |
| **Qual.** | The quality result: `pass` or a percentage score. |
| **Conf.** | The judge confidence, shown against the evaluator's threshold — for example `0.96 / 1.00`, a confidence of 0.96 against a threshold of 1.00. Confidence below the threshold routes the execution to Human Review. |
| **Verdict** | **Passed** or **Failed**. |
| **Routing** | **Auto-accepted** or **Human Review**. |
{% hint style="info" %}
### Routing depends on confidence, not the verdict
An execution routes to Human Review when confidence falls below the evaluator threshold. This can happen even when the verdict is *Passed*.
A *Failed* execution is auto-accepted when confidence meets the threshold. Routing reflects judge confidence, not the verdict.
{% endhint %}
---
# Agent Instructions
This documentation is published with GitBook. GitBook is the documentation platform designed so that both humans and AI agents can read, navigate, and reason over technical content effectively. Learn more at gitbook.com.
## Querying This Documentation
If you need additional information that is not directly available in this page, you can query the documentation dynamically by asking a question.
Perform an HTTP GET request on the current page URL with the `ask` query parameter, and the optional `goal` query parameter:
```
GET https://docs.uptiq.ai/control-center/evals/online-eval.md?ask=&goal=
```
`ask` is the immediate question: it should be specific, self-contained, and written in natural language.
`goal` is optional and describes the broader end goal you are ultimately trying to accomplish on behalf of the user. GitBook uses it to tailor the answer towards what is most useful for that goal.
The response will contain a direct answer to the question and relevant excerpts and sources from the documentation.
Use this mechanism when the answer is not explicitly present in the current page, you need clarification or additional context, or you want to retrieve related documentation sections.